

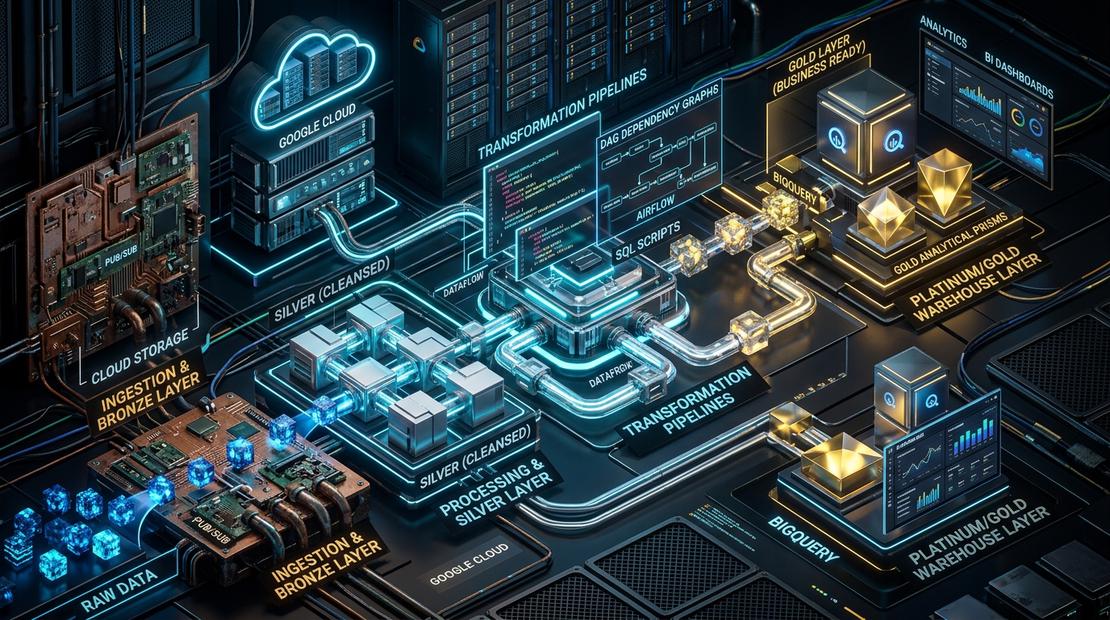
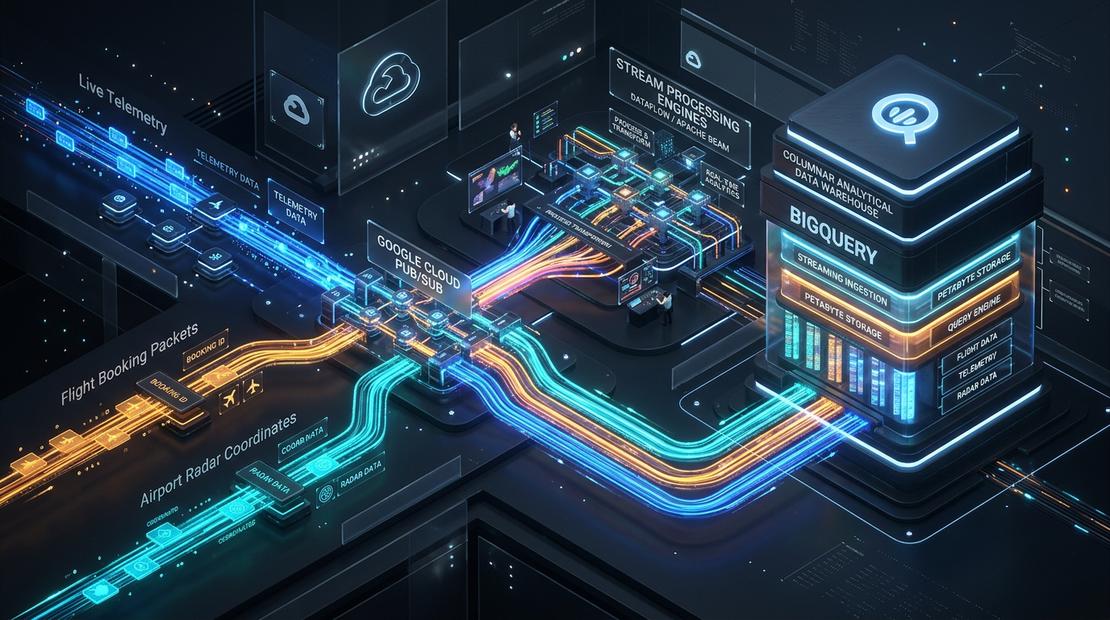
In Part 3 and Part 4, we built Offvia’s streaming ingestion path. Reservation events, cancellations, and seat updates now arrive in BigQuery and Cloud Storage continuously.
That is a good start—not the finish line.
On Monday morning, an executive dashboard reports negative gross ticket sales for Sunday. It also claims that flight OF-302 carried 400 passengers on an Airbus A320 with 180 seats. The streaming pipeline is healthy. The data is not.
Nothing “mysterious” happened in ingestion. It accepted what it was designed to accept: raw records from distributed producers. During a flash sale, Offvia saw duplicate retries, malformed refund payloads, and a fragile nightly stored procedure that attempted a full rebuild. The result was an expensive failure and untrustworthy reporting.
This article explains how to turn raw BigQuery landing data into dependable analytics with a Medallion transformation layer:
- Bronze for immutable raw events
- Silver for typed, deduplicated, conformed data
- Gold for business-ready marts
- Dataform or dbt for dependency-aware SQL workflows
- Incremental processing that handles late arrivals without repeatedly scanning all history
- Data-quality checks and quarantine paths that stop bad metrics from reaching dashboards
Important distinction: Dataform and dbt orchestrate and generate warehouse SQL. For BigQuery models, the actual transformation compute runs in BigQuery—not in Dataform or dbt itself. Dataform compiles workflow code, resolves dependencies, and runs the resulting actions in BigQuery. Dataform overview
The restaurant analogy
A high-volume restaurant does not plate dinner directly from the delivery dock.
[Loading dock]  ──>  [Prep station]  ──>  [Hot line]  ──>  [Dining room]
    Bronze              Silver              Gold           Consumers
- Bronze — loading dock: Preserve what arrived. Records can be duplicated, malformed, late, or not yet understood.
- Silver — prep station: Parse, cast, validate, deduplicate, standardize names and codes, and isolate exceptions.
- Gold — hot line: Deliver tables designed for a specific consumer: finance, operations, customer support, or BI.
The point is not the names Bronze, Silver, and Gold. The point is a deliberate contract between layers: raw data remains recoverable, conformed data becomes reusable, and business data becomes safe to consume.
Rule: Do not connect executive dashboards directly to raw ingestion tables. Raw data is evidence, not a reporting contract.
The architecture
┌──────────────────────────────────────────────────────────────────────┐
│ BRONZE: offvia_bronze                                                 │
│ Immutable, append-only records; raw JSON; arrival metadata; replayable│
└───────────────────────────────┬──────────────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────────────┐
│ TRANSFORMATION CONTROL PLANE                                          │
│ Dataform or dbt: Git, dependency graph, SQL compilation, tests, runs │
└───────────────────────────────┬──────────────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────────────┐
│ SILVER: offvia_silver                                                 │
│ Typed, deduplicated, validated entities and event tables              │
│ Plus: offvia_quarantine for rows needing investigation                │
└───────────────────────────────┬──────────────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────────────┐
│ GOLD: offvia_gold                                                     │
│ Facts, dimensions, aggregates, semantic reporting contracts           │
└───────────────────────────────┬──────────────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────────────┐
│ CONSUMPTION                                                           │
│ Looker / Looker Studio / BI Engine / ad-hoc analysis / reverse ETL   │
└──────────────────────────────────────────────────────────────────────┘
A healthy implementation also has operational boundaries:
- Separate service accounts and dataset permissions by environment.
- Source-controlled SQL, reviewed through pull requests.
- A repeatable full-refresh and backfill process.
- Observability for freshness, volumes, quality failures, and BigQuery cost.
- A quarantine destination and an explicit owner for remediation.
Dataform, dbt, or stored procedures?
Stored procedures remain useful for a small number of procedural tasks: administrative operations, tightly scoped transactions, or exceptional warehouse maintenance. They are not automatically bad. The problem is using one giant procedure as the entire transformation platform.
Dataform and dbt instead let you define individual data assets and their relationships. A call such as ${ref("stg_bookings")} in Dataform, or {{ ref("stg_bookings") }} in dbt, declares a dependency. The framework builds the directed acyclic graph (DAG), runs upstream models first, and exposes lineage.
| Dimension | BigQuery stored procedures | Google Cloud Dataform | dbt Core / dbt Cloud |
|---|---|---|---|
| Primary style | Imperative SQL scripting | SQLX plus optional JavaScript | SQL plus Jinja templating |
| Dependency graph | Manual or external orchestration | Native ref() graph | Native ref() graph |
| Transformation runtime | BigQuery | BigQuery | Your warehouse, such as BigQuery |
| Managed service | BigQuery only | Managed Google Cloud service | Core needs a runner; Cloud is managed SaaS |
| Data-quality tests | Hand-written SQL | Built-in assertions and custom assertions | YAML tests and custom tests |
| Portability | BigQuery-specific | BigQuery-focused | Broad adapter ecosystem |
| Best fit | Targeted procedural work | BigQuery-first teams wanting minimal platform overhead | Multi-platform estates or teams invested in dbt packages and conventions |
What Dataform actually does
Dataform uses SQLX and configuration to define tables, views, incremental tables, assertions, dependencies, documentation, and workflow operations. It compiles those definitions into BigQuery SQL, resolves missing or circular dependencies, builds the dependency graph, and runs the resulting actions in BigQuery. It can also integrate with Git and schedule workflows through workflow configurations. Dataform overview
One correction to a common description: compilation is not a guarantee that every referenced BigQuery column or type has been validated through a free warehouse dry run. Treat Dataform compilation as code and dependency validation. Validate query semantics and cost separately with BigQuery query validation, CI checks, controlled executions, and sensible test data.
A practical decision
Choose Dataform when the warehouse is BigQuery, native Google Cloud IAM and a managed console workflow matter, and you want the fewest moving parts.
Choose dbt when portability, its package ecosystem, standardized analytics-engineering practices, or an existing dbt platform are important. On BigQuery, dbt supports incremental strategies such as merge and insert_overwrite; choose the strategy around the table’s update pattern and partition design. dbt BigQuery configurations
Use stored procedures sparingly as supporting tools, not as a replacement for model-level lineage, testing, review, and deployment practices.
Bronze: preserve the evidence
Bronze is not “bad data.” It is a defensible historical record of what the platform received.
For an event table such as offvia_bronze.raw_booking_events, retain at least:
raw_payload: the original JSON payload or raw recordingested_at: a trustworthy arrival timestamp assigned by the platformsource_system: producer or partner identifierevent_idor message identifier, when availablemessage_published_at: producer-side publish time, when availableschema_version: payload contract version- tracing fields such as a Pub/Sub message ID or correlation ID
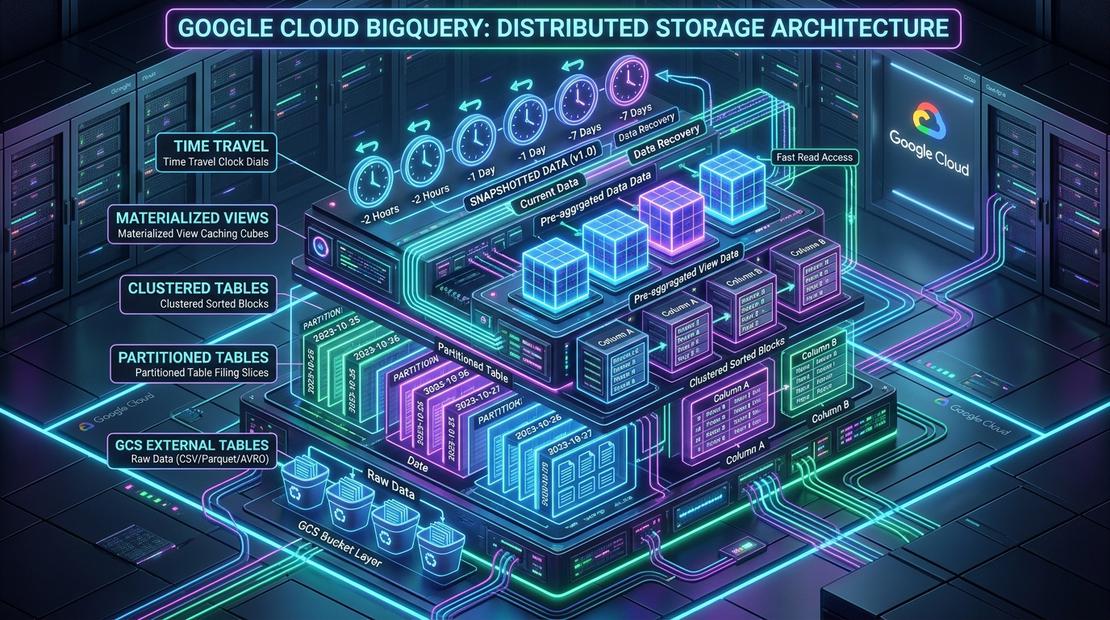
Partition Bronze by an ingestion-derived date and set an appropriate retention policy. Cluster only when query patterns justify it. Do not overwrite it as part of normal transformations; its job is replayability and auditability.
Silver: make data trustworthy and reusable
Silver models turn opaque payloads into typed records. This is where you:
- Extract JSON fields.
- Use
SAFE_CASTand safe parsing for untrusted input. - Normalize currency codes, status values, airport identifiers, and time zones.
- Deduplicate deliveries.
- Separate records that cannot meet the conformed contract.
- Preserve operational metadata such as
ingested_at, source, and original event IDs.
Use two timestamps for two questions
event_timestamp answers: When did the business event occur?
ingested_at answers: When did our platform receive this record?
For incremental extraction, prefer a reliable arrival or change timestamp such as ingested_at; otherwise, a late event can be permanently missed. For business reporting, partitioning, and historical analysis, use the business event date where it reflects the intended grain.
This does not mean “filter only with ingested_at > MAX(ingested_at) forever.” That exclusive watermark pattern can fail when data arrives late, a run partially fails, timestamps collide, or corrections update older business dates. Production pipelines need an overlap window and an idempotent merge or partition rebuild strategy.
A safer incremental Dataform pattern
The following model uses a three-day ingestion lookback. It re-reads a bounded overlap of Bronze, keeps the newest delivered version per booking_id, and lets Dataform merge using the declared uniqueKey. The lookback makes retries and delayed arrivals recoverable; the deduplication makes reprocessing safe.
-- definitions/silver/stg_bookings.sqlx
config {
  type: "incremental",
  schema: "offvia_silver",
  name: "stg_bookings",
  uniqueKey: ["booking_id"],
  bigquery: {
    partitionBy: "DATE(booking_timestamp)",
    clusterBy: ["origin_airport", "destination_airport"]
  },
  assertions: {
    uniqueKey: ["booking_id"],
    nonNull: ["booking_id", "passenger_id", "flight_id", "booking_timestamp"],
    rowConditions: [
      "total_amount >= 0",
      "currency IN ('EUR', 'USD', 'GBP')"
    ]
  }
}

WITH source_rows AS (
  SELECT
    JSON_VALUE(raw_payload, '$.booking_id') AS booking_id,
    JSON_VALUE(raw_payload, '$.passenger_id') AS passenger_id,
    JSON_VALUE(raw_payload, '$.flight_id') AS flight_id,
    SAFE_CAST(JSON_VALUE(raw_payload, '$.booking_timestamp') AS TIMESTAMP) AS booking_timestamp,
    SAFE_CAST(JSON_VALUE(raw_payload, '$.total_amount') AS NUMERIC) AS total_amount,
    JSON_VALUE(raw_payload, '$.currency') AS currency,
    JSON_VALUE(raw_payload, '$.booking_status') AS booking_status,
    JSON_VALUE(raw_payload, '$.origin_airport') AS origin_airport,
    JSON_VALUE(raw_payload, '$.destination_airport') AS destination_airport,
    ingested_at
  FROM ${ref("raw_bookings")}
  WHERE
    ${when(
      incremental(),
      "ingested_at >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 3 DAY)",
      "TRUE"
    )}
),

valid_candidates AS (
  SELECT *
  FROM source_rows
  WHERE booking_id IS NOT NULL
    AND booking_timestamp IS NOT NULL
),

deduplicated AS (
  SELECT * EXCEPT (row_number)
  FROM (
    SELECT
      *,
      ROW_NUMBER() OVER (
        PARTITION BY booking_id
        ORDER BY booking_timestamp DESC, ingested_at DESC
      ) AS row_number
    FROM valid_candidates
  )
  WHERE row_number = 1
)

SELECT *
FROM deduplicated
Dataform supports incremental tables and applies incremental logic after the first full build. Its documentation recommends expressing the incremental subset in the model’s conditional WHERE clause. Create tables in Dataform
The important caveats
Select the winner deliberately. Ordering by
booking_timestamp DESC, ingested_at DESCassumes the latest event timestamp represents the desired booking state. A stronger approach uses an immutable producer revision, sequence number, or event version when the source provides one.Keep rejected rows.
SAFE_CASTprevents a job failure, but it can silently produceNULL. Send malformed or invalid records tooffvia_quarantine.invalid_booking_events, including the raw payload, reason codes, andingested_at.Do not confuse assertions with quarantine. Dataform assertions find violating rows and fail when their query returns rows. They are excellent signals and release gates; they do not themselves route rows to a quarantine table. Build quarantine explicitly upstream, then assert that the published Silver and Gold contracts are clean. Test data quality in Dataform
Choose your assertion policy. A failed assertion is not automatically a reason to let a bad Gold mart publish. For critical financial metrics, fail the publication or promote only a previously approved version. For noncritical anomalies, alert, quarantine, and keep the last known good table available. This is a business SLA decision.
Incremental models: correctness before cost
An incremental model is a maintenance strategy, not a magic performance switch.
For a BigQuery MERGE that updates or deletes rows, cost includes bytes read by the DML plus the size of the target data or target partitions affected. On partitioned tables, limiting the scanned partitions reduces the relevant target component. BigQuery DML pricing behavior
Partition pruning in a merge
When the target is partitioned by booking_date, constrain the target side to the range that can actually change:
MERGE `project.offvia_silver.stg_bookings` AS T
USING `project.offvia_work.stg_bookings_delta` AS S
ON T.booking_id = S.booking_id
AND T.booking_date >= DATE_SUB(CURRENT_DATE(), INTERVAL 7 DAY)
WHEN MATCHED THEN
  UPDATE SET
    passenger_id = S.passenger_id,
    flight_id = S.flight_id,
    booking_timestamp = S.booking_timestamp,
    total_amount = S.total_amount,
    currency = S.currency,
    booking_status = S.booking_status,
    ingested_at = S.ingested_at
WHEN NOT MATCHED THEN
  INSERT (
    booking_id, passenger_id, flight_id, booking_timestamp,
    total_amount, currency, booking_status, ingested_at
  )
  VALUES (
    S.booking_id, S.passenger_id, S.flight_id, S.booking_timestamp,
    S.total_amount, S.currency, S.booking_status, S.ingested_at
  );
This is only correct if the seven-day target window matches the actual correction and late-arrival policy. Do not add a target date predicate merely to save money if it makes older corrections insert duplicates or fail to update. BigQuery supports partition pruning for MERGE when the partitioning column is filtered in an applicable source filter, search condition, or merge condition. Update partitioned tables with DML
For date-partitioned facts, consider a bounded partition-rebuild pattern rather than row-level merging: rebuild the affected recent partitions using insert_overwrite in dbt or an equivalent atomic replace strategy. This often fits append-heavy event data better than frequent updates against a very large target.
Late arrivals must invalidate Gold
A Silver model can correctly absorb a late booking while Gold remains wrong if Gold only refreshes today’s partition. The pipeline must propagate the set of affected business dates—for example, DATE(booking_timestamp) or flight_date—and rebuild those Gold partitions.
A robust operating policy usually includes:
- A normal rolling lookback, such as three to seven days.
- A scheduled wider reconciliation, such as monthly, for known source behavior.
- An explicit targeted backfill path for exceptional historical corrections.
- A data-freshness monitor that detects missing or delayed source delivery.
Quality checks that protect reporting
Data-quality checks should be layered, cheap enough to run, and meaningful to the business.
| Layer | Examples | Action when it fails |
|---|---|---|
| Bronze | Unexpected source volume, schema-version change, malformed JSON rate | Alert; preserve input; investigate producer contract |
| Silver | Non-null IDs, valid timestamps, allowed currency/status, one canonical version per key | Quarantine invalid rows; fail critical contract checks |
| Gold | Revenue is non-negative where required, passenger count does not exceed capacity, complete date coverage | Block or roll back publication of affected mart; alert data owner |
Example: capacity assertion
-- definitions/assertions/assert_route_capacity.sqlx
config {
  type: "assertion",
  schema: "offvia_quality"
}

SELECT
  flight_date,
  flight_id,
  total_passengers_booked,
  seat_capacity
FROM ${ref("fct_daily_route_profitability")}
WHERE total_passengers_booked > seat_capacity
A Dataform assertion is a query that must return zero rows; any returned row is a failure. Assertions can be declared in a model configuration or written as dedicated SQLX assertion files. Test data quality in Dataform
Avoid expensive “check the entire history every hour” tests. Scope checks to changed partitions where possible, and schedule full reconciliations at a frequency that matches risk and budget.
Gold: model for consumers
Gold is not just “another cleaned table.” It is a product with a declared grain, ownership, quality contract, and performance expectations.
For Offvia, a route-performance mart could have one row per flight or one row per route per day. Do not mix the two. The model below uses one row per flight because it groups by flight_id; call it a flight-performance mart, then aggregate separately if route/day is the intended dashboard grain.
-- definitions/gold/fct_flight_performance.sqlx
config {
  type: "table",
  schema: "offvia_gold",
  name: "fct_flight_performance",
  bigquery: {
    partitionBy: "flight_date",
    clusterBy: ["carrier_code", "origin_airport", "destination_airport"]
  },
  tags: ["gold_marts", "executive_reporting"]
}

WITH flight_bookings AS (
  SELECT
    DATE(f.departure_scheduled_time) AS flight_date,
    f.flight_id,
    f.carrier_code,
    f.flight_number,
    f.origin_airport,
    f.destination_airport,
    f.aircraft_model,
    f.seat_capacity,
    COUNT(DISTINCT b.booking_id) AS total_passengers_booked,
    COALESCE(SUM(b.total_amount), 0) AS total_gross_revenue,
    COALESCE(AVG(b.total_amount), 0) AS average_ticket_price
  FROM ${ref("stg_flights")} AS f
  LEFT JOIN ${ref("stg_bookings")} AS b
    ON f.flight_id = b.flight_id
   AND b.booking_status IN ("CONFIRMED", "CHECKED_IN")
  GROUP BY 1, 2, 3, 4, 5, 6, 7, 8
)

SELECT
  flight_date,
  flight_id,
  carrier_code,
  flight_number,
  origin_airport,
  destination_airport,
  aircraft_model,
  seat_capacity,
  total_passengers_booked,
  ROUND(SAFE_DIVIDE(total_passengers_booked, seat_capacity) * 100, 2) AS seat_occupancy_percentage,
  total_gross_revenue,
  average_ticket_price,
  CASE
    WHEN SAFE_DIVIDE(total_passengers_booked, seat_capacity) >= 0.85 THEN "HIGH_PROFIT"
    WHEN SAFE_DIVIDE(total_passengers_booked, seat_capacity) >= 0.60 THEN "BREAK_EVEN"
    ELSE "UNDERPERFORMING"
  END AS route_performance_tier,
  CURRENT_TIMESTAMP() AS transformed_at
FROM flight_bookings
Star schema or One Big Table?
| Pattern | Strengths | Trade-offs | Use it when |
|---|---|---|---|
| Star schema | Reusable dimensions, clean historical modeling, reduced duplication | Consumers may need joins; semantic governance matters | Many domains share dimensions, or slowly changing dimensions are important |
| One Big Table (OBT) | Easy BI consumption, fewer runtime joins, predictable dashboard queries | Duplicates attributes and makes dimension corrections/backfills heavier | A specific dashboard or exploration workload needs a stable denormalized contract |
BigQuery can serve both patterns well. A practical compromise is to maintain conformed dimensions and facts in Silver/Gold, then publish purpose-built wide reporting tables only where dashboard latency, simplicity, or concurrency makes them valuable.
Production checklist
Before calling the transformation layer production-ready, verify these points:
- Bronze is immutable, replayable, and carries ingestion metadata.
- Every Silver entity has an explicit key, grain, deduplication rule, and late-arrival policy.
- Malformed and rejected records go to a queryable quarantine dataset with reason codes.
- Incremental models use a bounded overlap window and are idempotent.
MERGEor partition replacement scans only the partitions that can legitimately change.- Late-arriving events cause downstream business-date partitions to refresh.
- Gold tables declare their grain in documentation and enforce business invariants.
- Critical assertion failures prevent bad data from becoming the new published reporting state.
- SQL, tests, schedules, permissions, and deployment configuration are version-controlled and reviewed.
- Dashboards query Gold tables or governed semantic models—not Bronze.
- Cost, freshness, volume, assertion failures, and quarantine rates are monitored.
Final takeaways
The transformation layer is where an ingestion platform becomes a trusted data platform.
Offvia’s negative revenue and impossible seat count are not primarily SQL problems. They are contract problems: raw retries were treated as bookings, malformed values were allowed into revenue logic, and a monolithic rebuild had no safe deployment or validation boundary.
A Medallion design makes those boundaries explicit. Bronze retains evidence. Silver creates reliable, reusable entities. Gold publishes business contracts. Dataform or dbt turns individual SQL models into a reviewable, dependency-aware workflow, while BigQuery performs the heavy compute.
In Part 6, we will build this foundation: create a Dataform repository, define Bronze-to-Silver-to-Gold SQLX models, add assertions and quarantine handling, and automate execution through a production-friendly release workflow.
Community Discussion 0